
Navigating the turbulent waters of IT operations often means confronting unexpected outages, critical system failures, or security breaches that can bring business processes to a grinding halt. Such events, deemed major incidents, demand swift resolution and a thorough post-mortem analysis to prevent recurrence. This is precisely where an It Major Incident Report Template becomes an indispensable tool, transforming chaos into structured learning and providing a standardized framework for documenting, analyzing, and communicating the details surrounding high-impact disruptions.
Without a well-defined process for incident reporting, organizations risk repeating past mistakes, struggling with accountability, and failing to extract valuable insights from challenging situations. A template ensures consistency, clarity, and completeness in documentation, allowing teams to systematically capture every relevant piece of information from the initial detection to the final resolution and follow-up actions. It serves not just as a historical record, but as a critical component of an organization’s continuous improvement efforts and overall IT service management (ITSM) strategy.
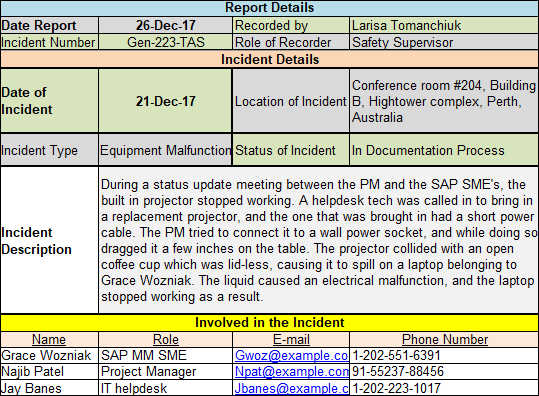
The scope of a major incident can range from a complete network collapse to a critical application failure impacting thousands of users, or a data breach compromising sensitive information. Regardless of the specific nature, the common thread is a significant disruption to business operations, demanding an immediate, coordinated response. The subsequent report is the bridge between the immediate firefighting and the long-term strategic improvements.
This article will delve into the profound importance of a structured reporting mechanism, dissect the essential components that make an incident report robust and useful, and offer best practices for leveraging an It Major Incident Report Template to enhance operational resilience and drive service excellence. By understanding and implementing a comprehensive template, IT teams can move beyond reactive problem-solving towards a proactive, learning-oriented approach to incident management. It’s about turning every major incident from a setback into an opportunity for growth and stronger infrastructure.

Understanding IT Major Incidents
Before diving into the report itself, it’s crucial to define what constitutes a major incident in an IT context. A major incident is typically characterized by its significant impact on business operations, customers, or revenue, demanding an immediate and coordinated response. It’s not merely a service degradation; it’s a disruption that causes considerable harm and often requires resources from multiple teams to resolve. The criteria for a major incident usually include high severity and a wide scope of impact.

Common examples of major incidents include widespread network outages, critical application failures affecting core business functions, significant data loss or corruption, severe security breaches, and prolonged system downtime. Identifying these events promptly and accurately is the first step in effective incident management. The ability to distinguish between routine incidents and major incidents dictates the level of response and the subsequent reporting requirements. Clear definitions, often established within an organization’s ITSM policies, are vital for consistent identification.
Why an IT Major Incident Report Template is Indispensable
The value of a structured approach to incident reporting cannot be overstated. An It Major Incident Report Template provides numerous benefits, extending far beyond simple documentation. It acts as a cornerstone for several critical IT and business functions, fostering transparency, accountability, and continuous improvement.
Firstly, it ensures consistency and completeness. Without a template, different individuals might report incidents in varying formats, omitting crucial details or providing inconsistent information. A standardized template guarantees that all necessary data points are captured, from initial detection to root cause analysis and resolution steps. This consistency is vital for accurate historical tracking and trend analysis.
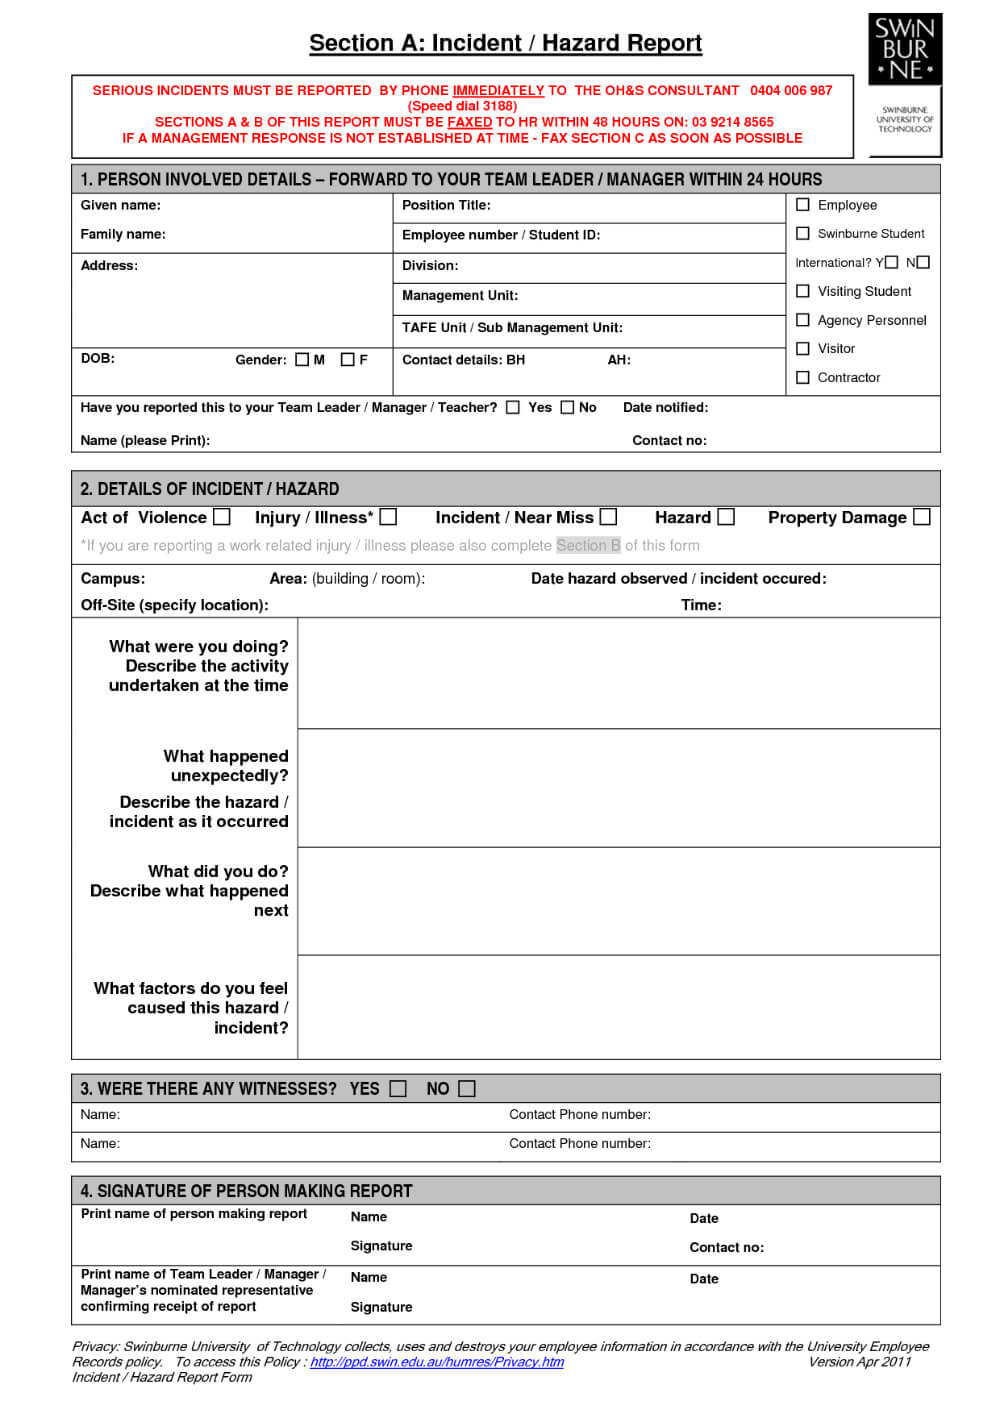
Secondly, templates facilitate effective communication. During and after a major incident, clear and concise communication is paramount. The structured nature of a template allows for quick summarization of key facts for stakeholders, translating complex technical details into understandable business impacts. This aids in managing expectations, providing timely updates, and maintaining trust with affected parties.
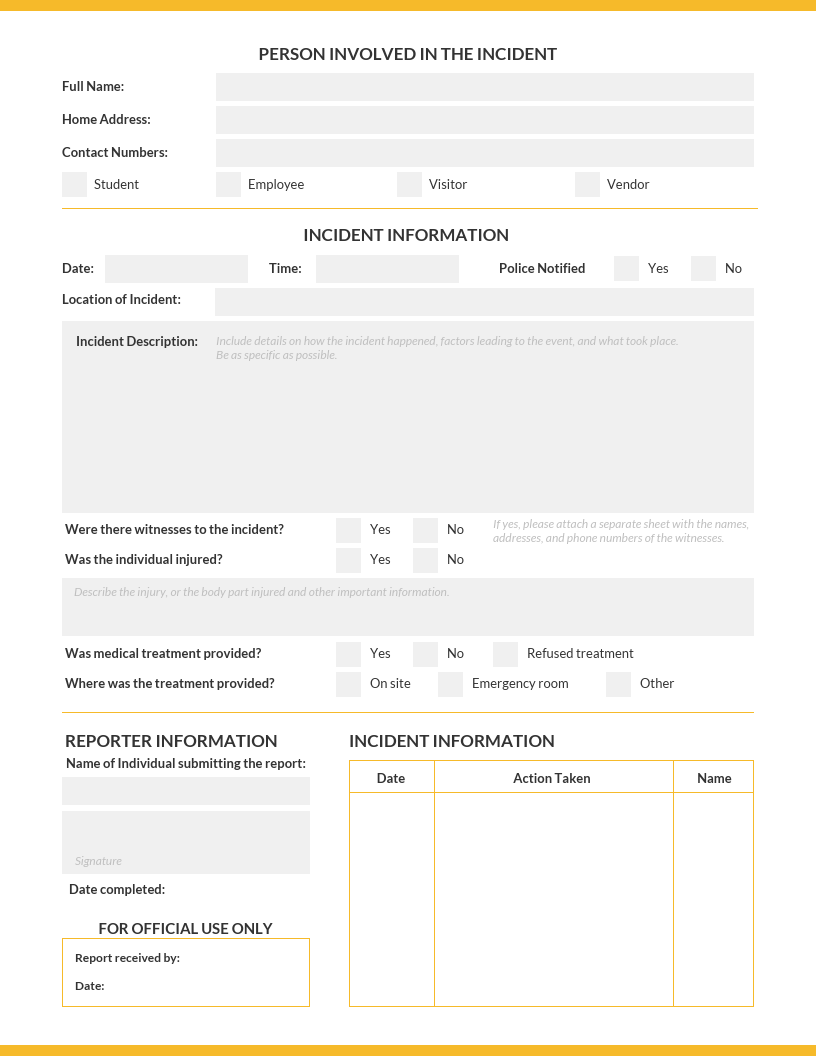
Thirdly, it supports root cause analysis and problem management. The primary goal of a major incident report isn’t just to document what happened, but to understand why it happened. A template guides the team through a systematic investigation, prompting them to identify the underlying causes rather than just addressing symptoms. This detailed analysis is the foundation for effective problem management, preventing similar incidents in the future.
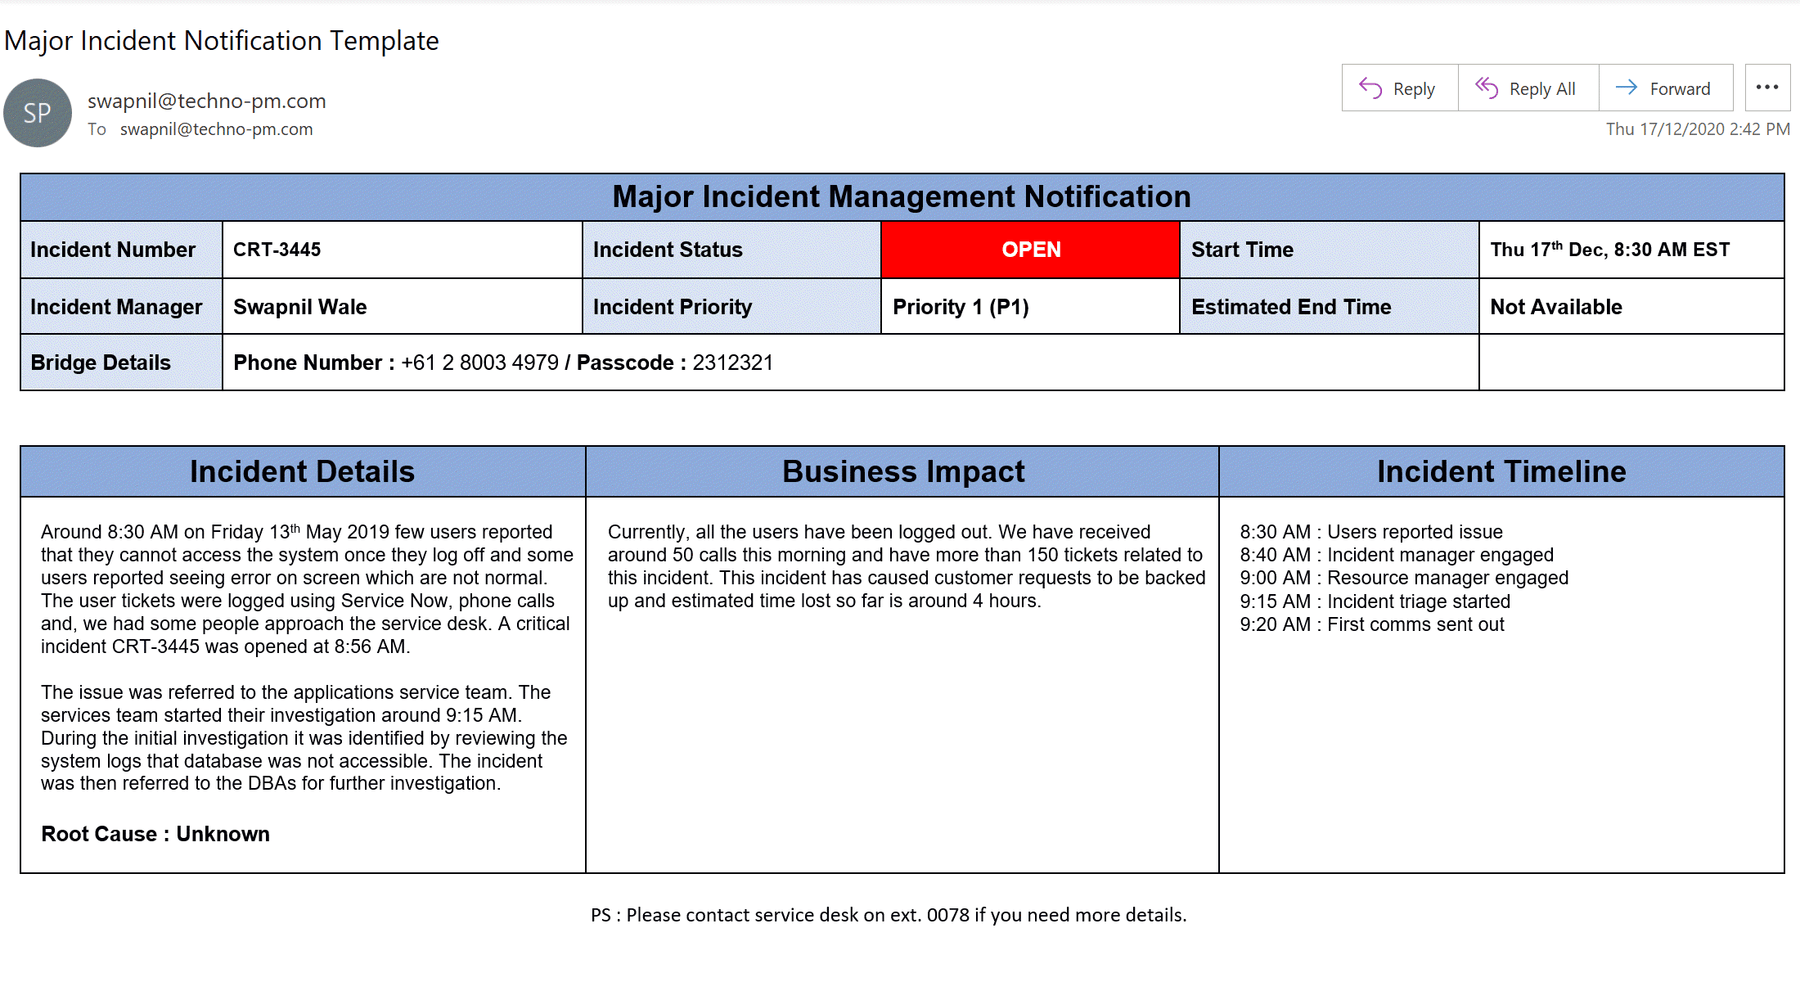
Finally, an It Major Incident Report Template is crucial for learning and continuous improvement. Each major incident represents a learning opportunity. By analyzing trends across multiple reports, organizations can identify recurring issues, weaknesses in their infrastructure or processes, and areas where preventative measures need to be strengthened. This iterative learning process drives service maturity, enhances operational resilience, and reduces the likelihood and impact of future incidents.
Key Components of an Effective IT Major Incident Report Template
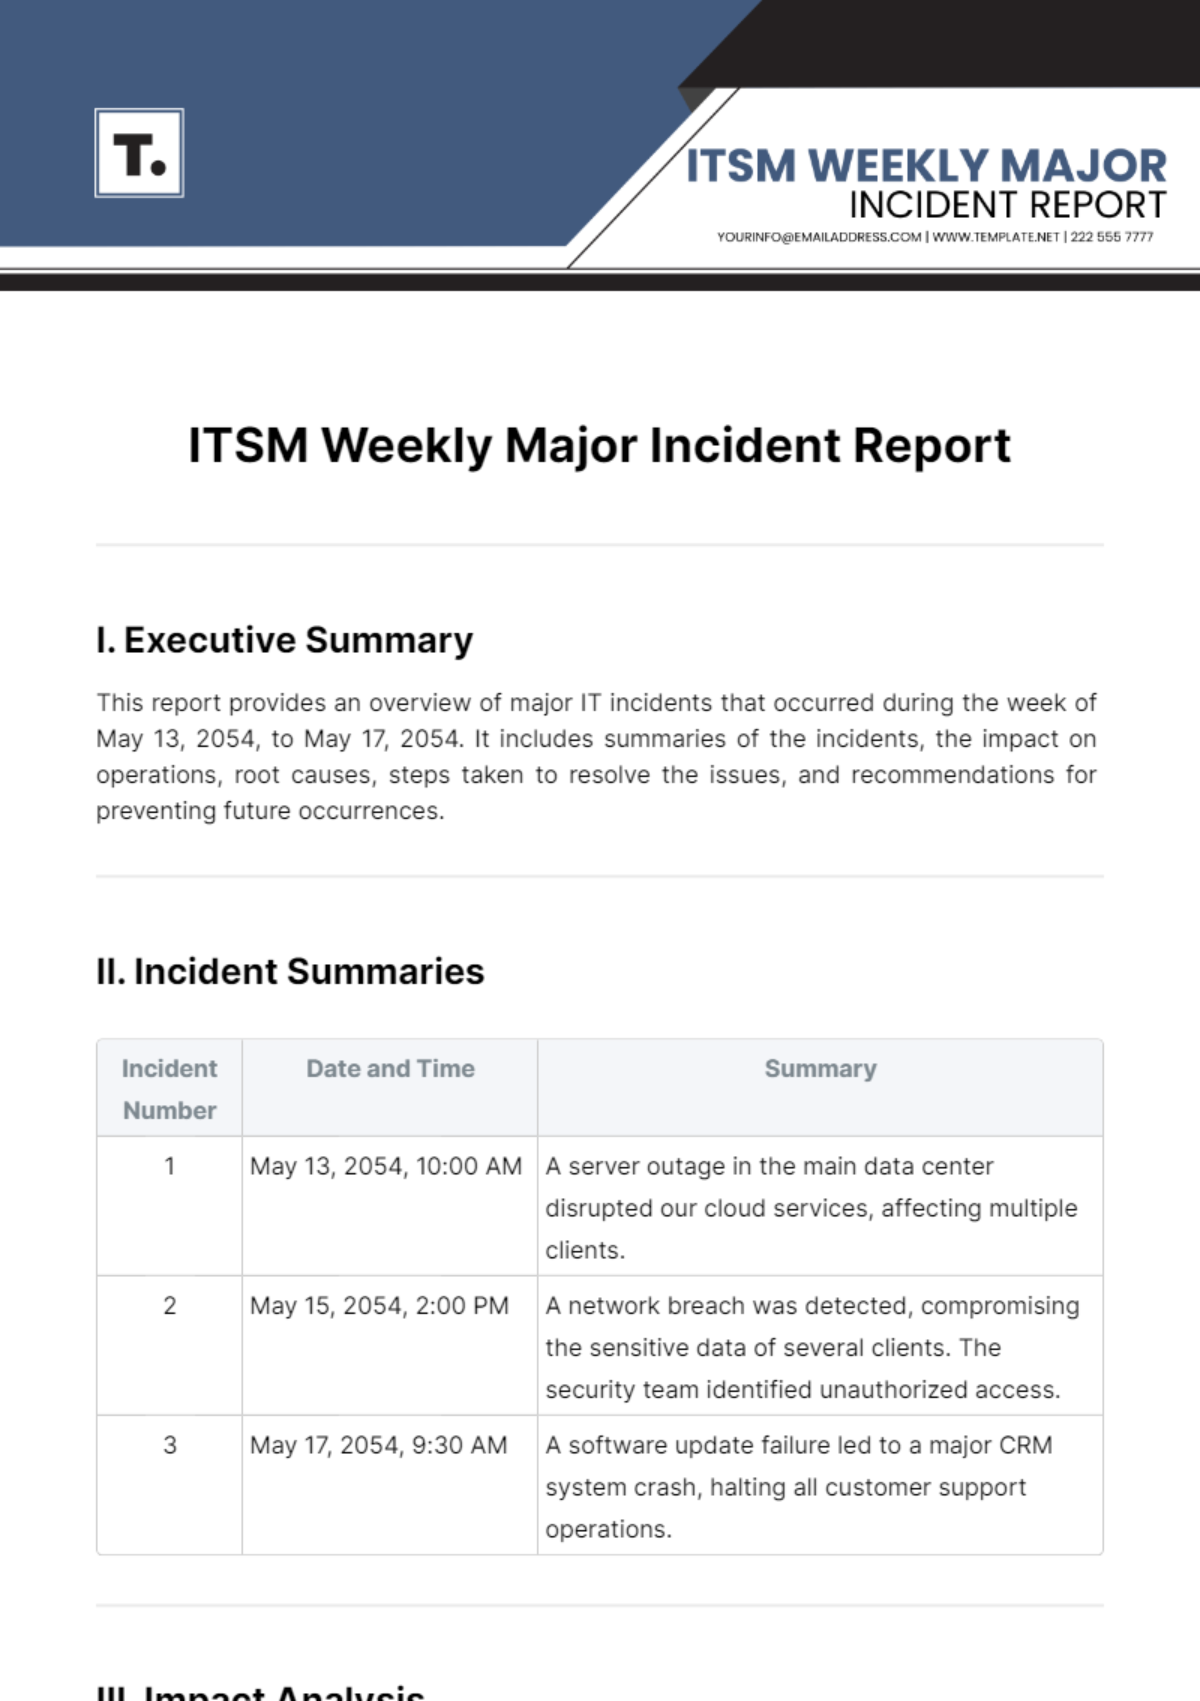
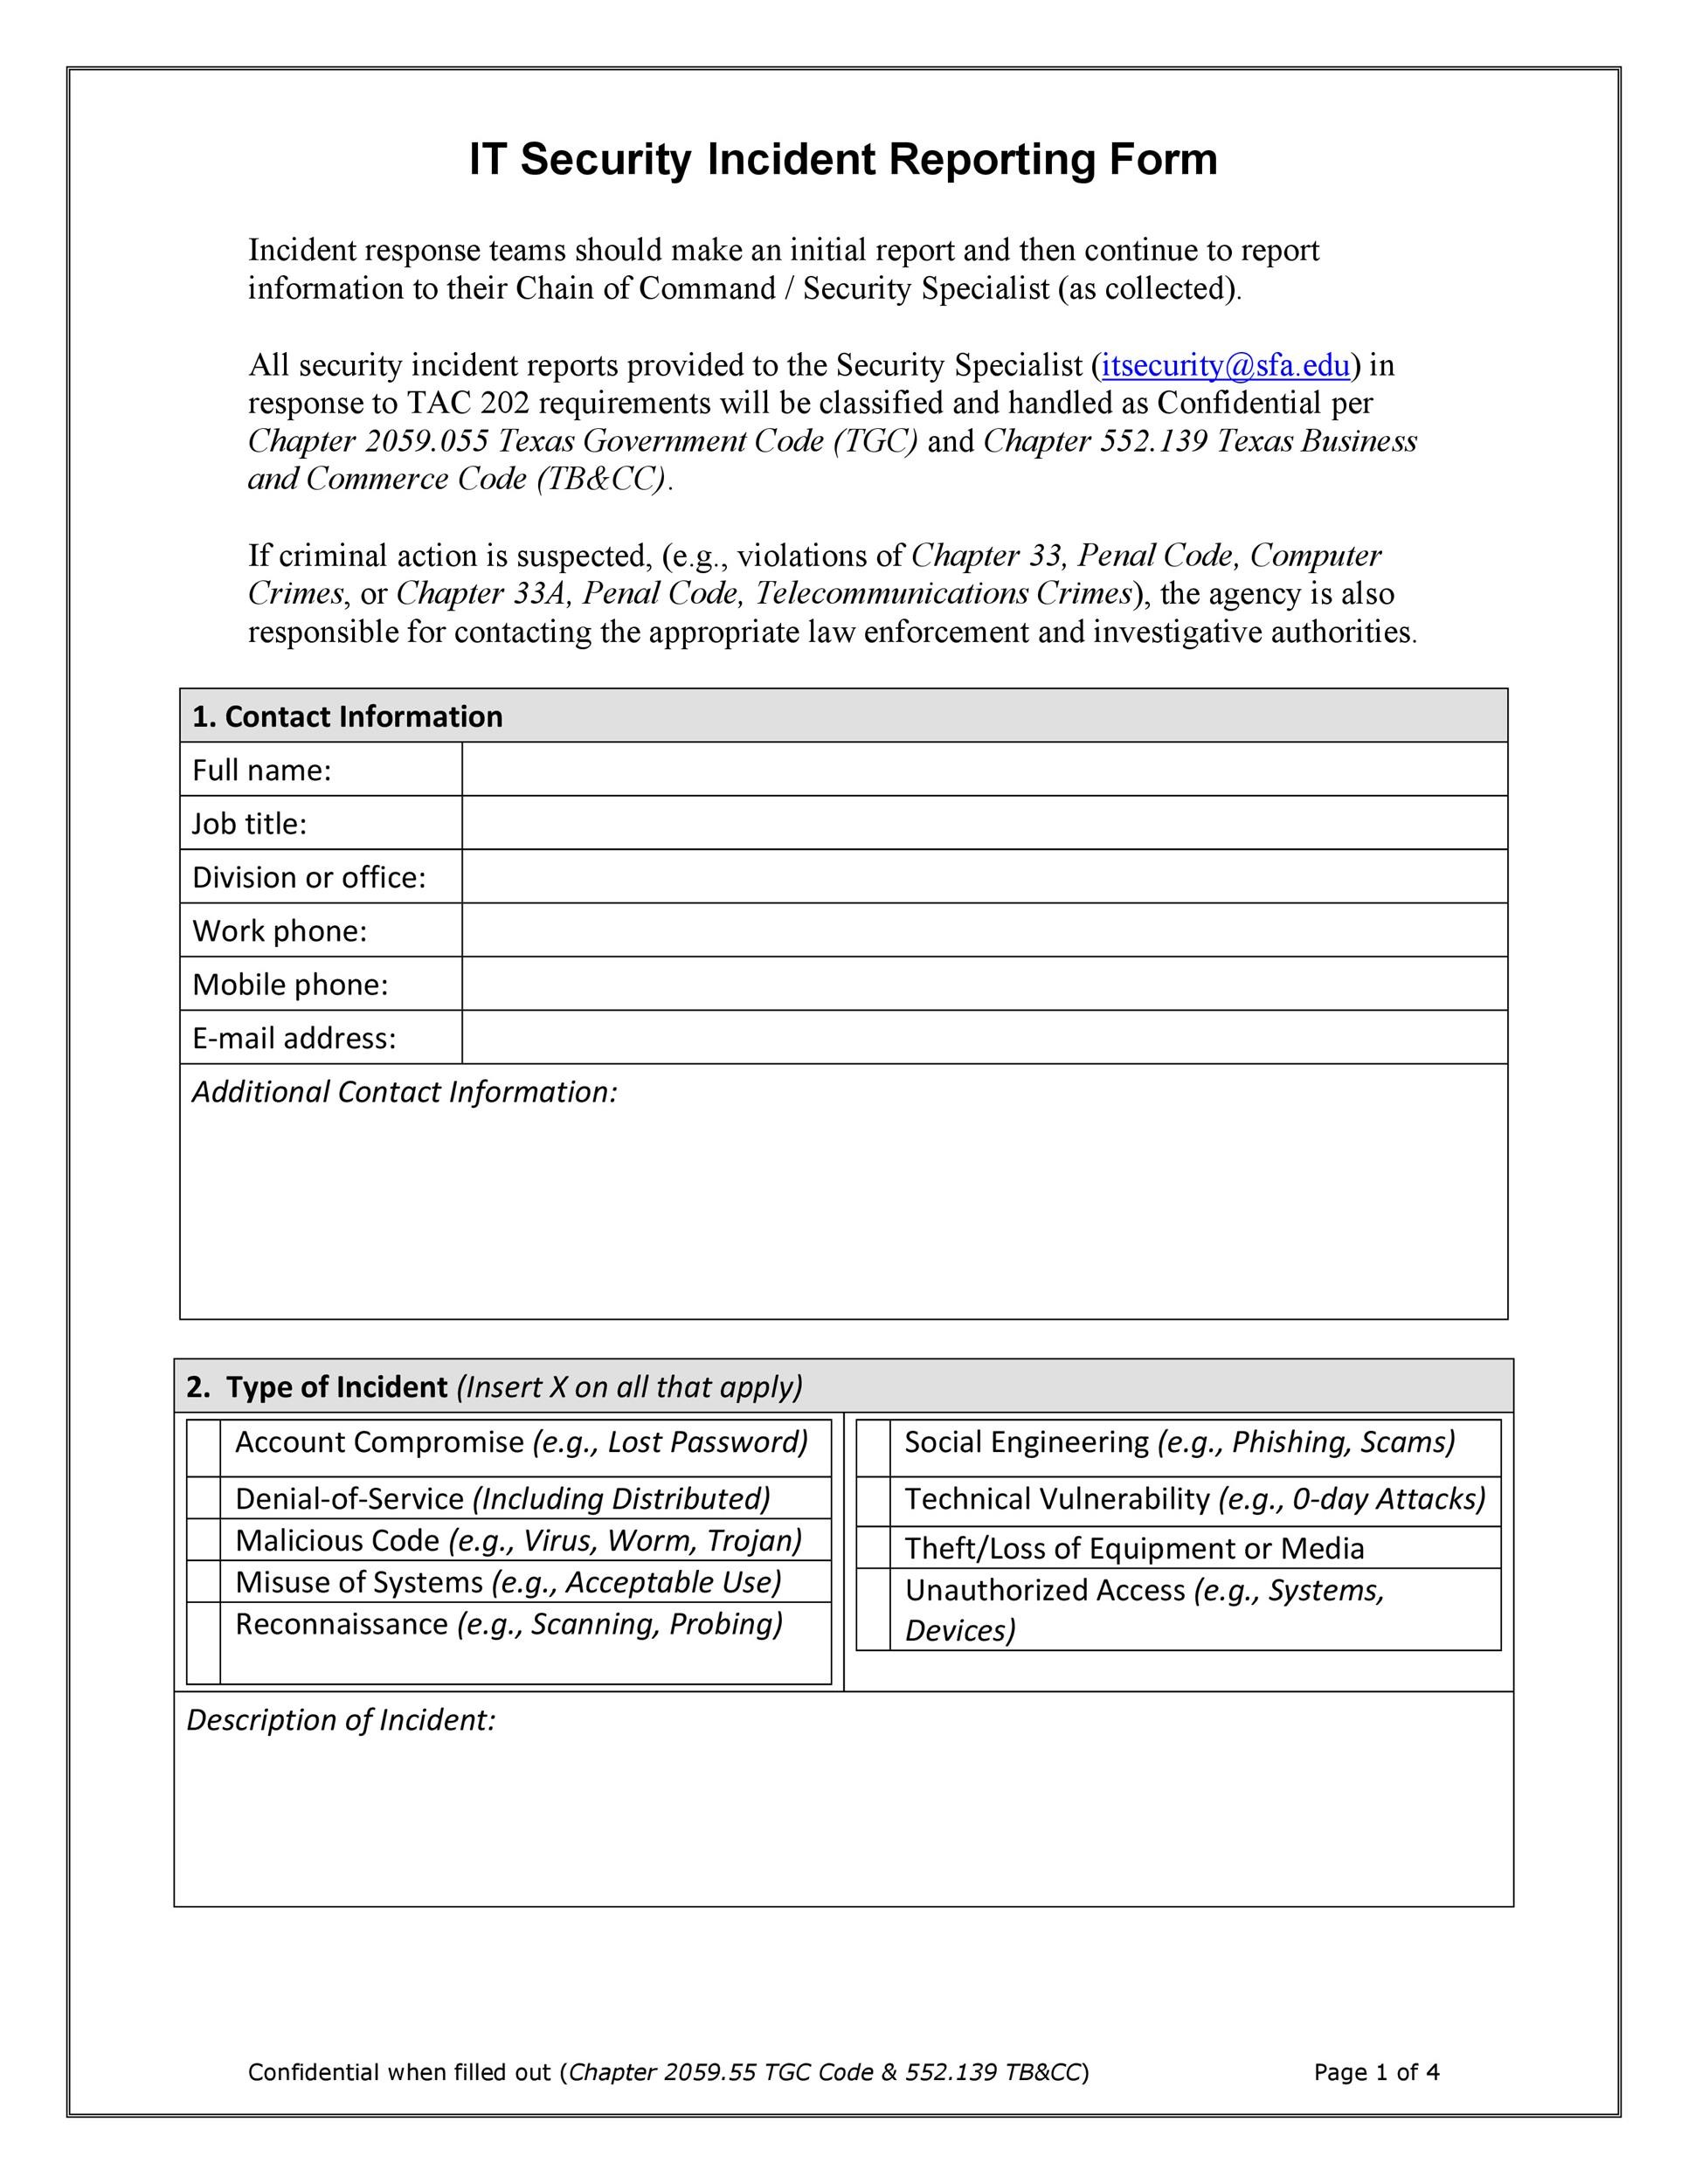
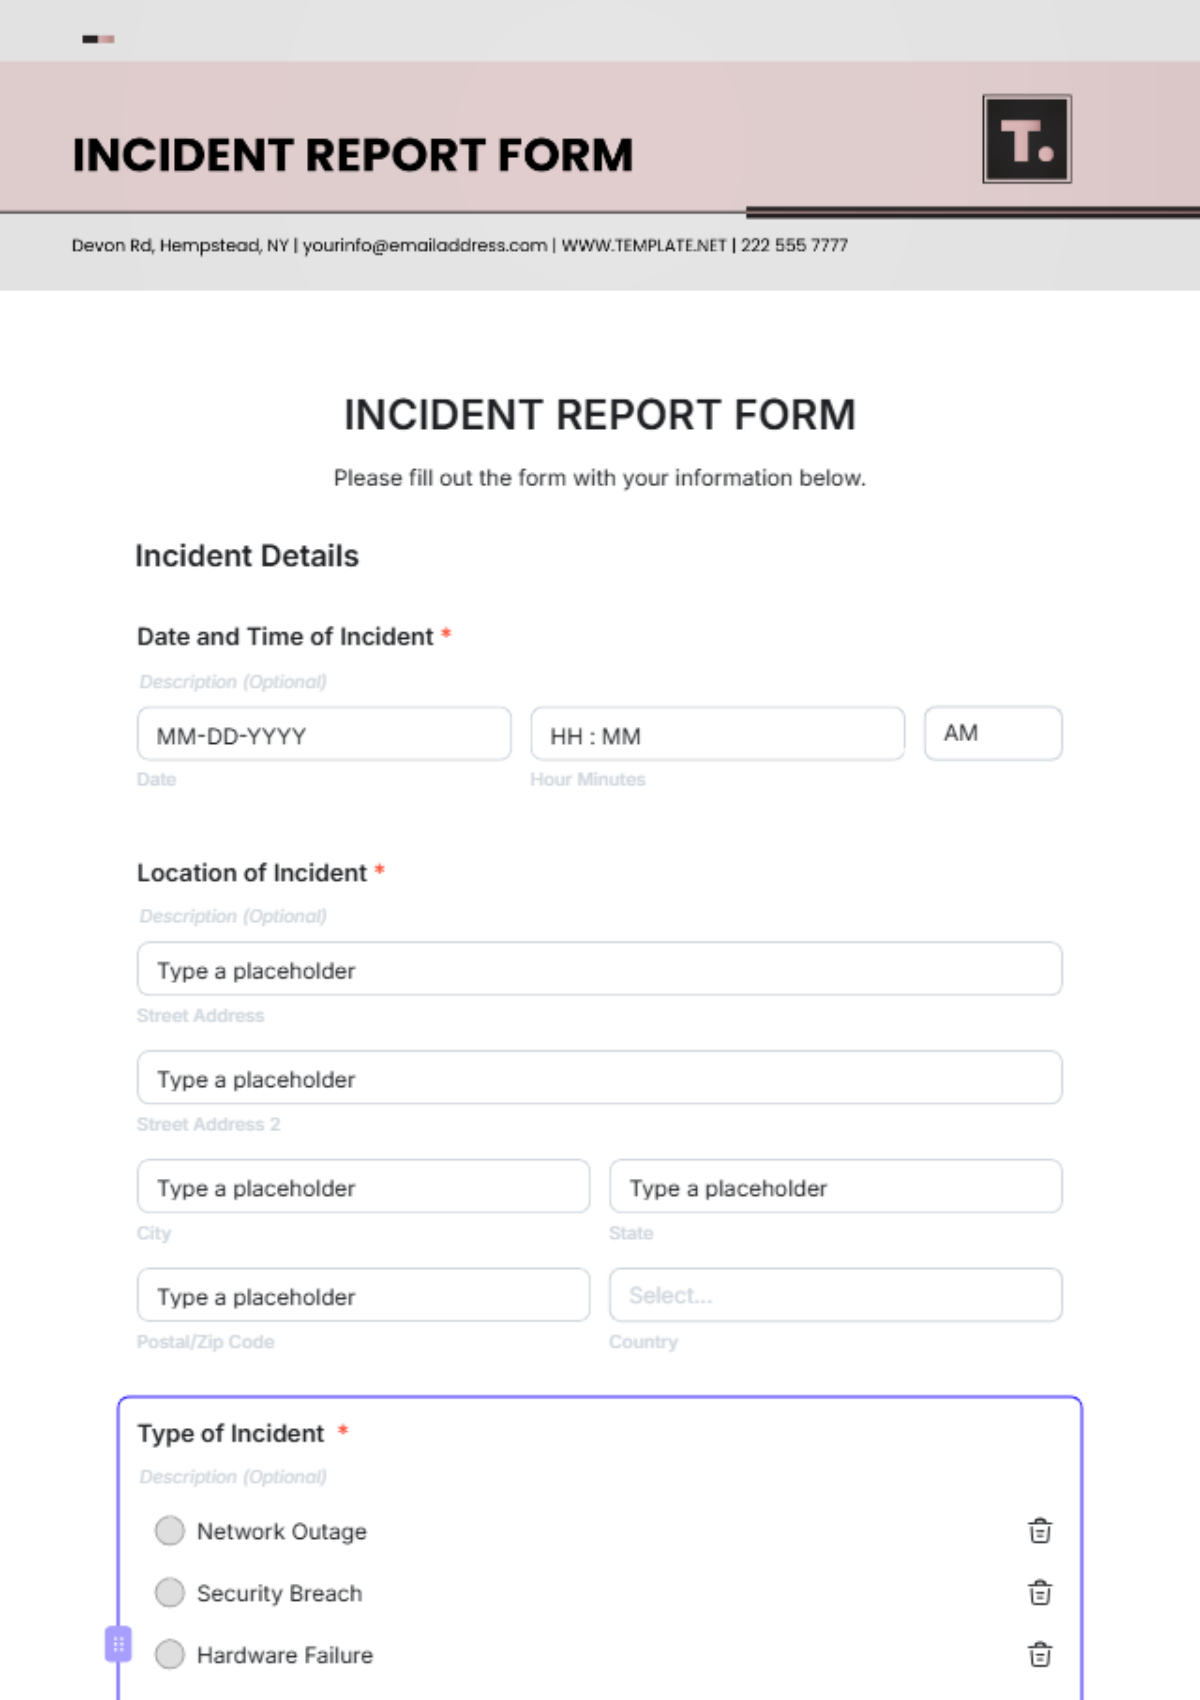
A robust It Major Incident Report Template is designed to capture all essential information required for analysis, communication, and future prevention. While specific fields may vary based on organizational needs and industry, several core components are universally critical.
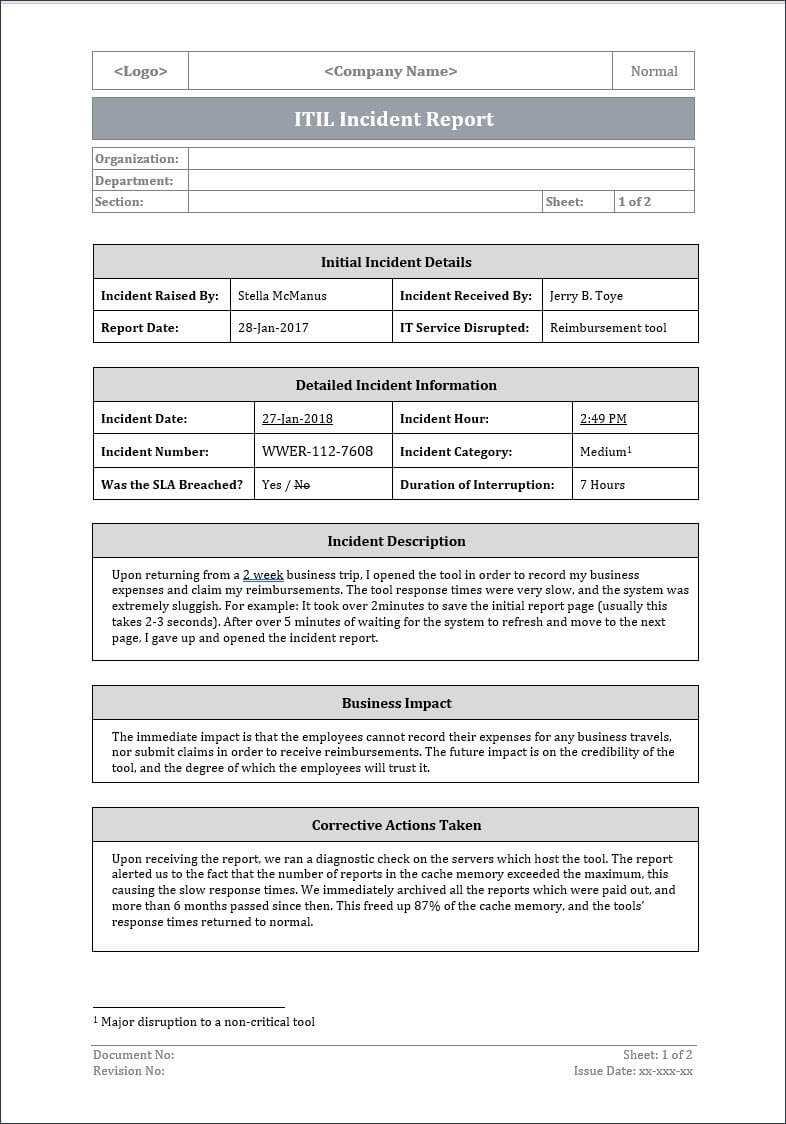
Incident Identification and Overview
- Incident ID: A unique identifier for tracking purposes.
- Date and Time of Detection: When the incident was first identified.
- Date and Time of Start: When the incident actually began (if different from detection).
- Date and Time of Resolution: When the service was fully restored.
- Duration: Total time the service was impacted.
- Incident Title/Summary: A concise, high-level description of the incident.
- Severity/Impact Level: Categorization (e.g., Critical, High, Medium) based on predefined criteria outlining the business impact.
- Affected Services/Systems: List all applications, infrastructure components, or business services impacted.
- Impacted Users/Customers: Number or type of users/customers affected.
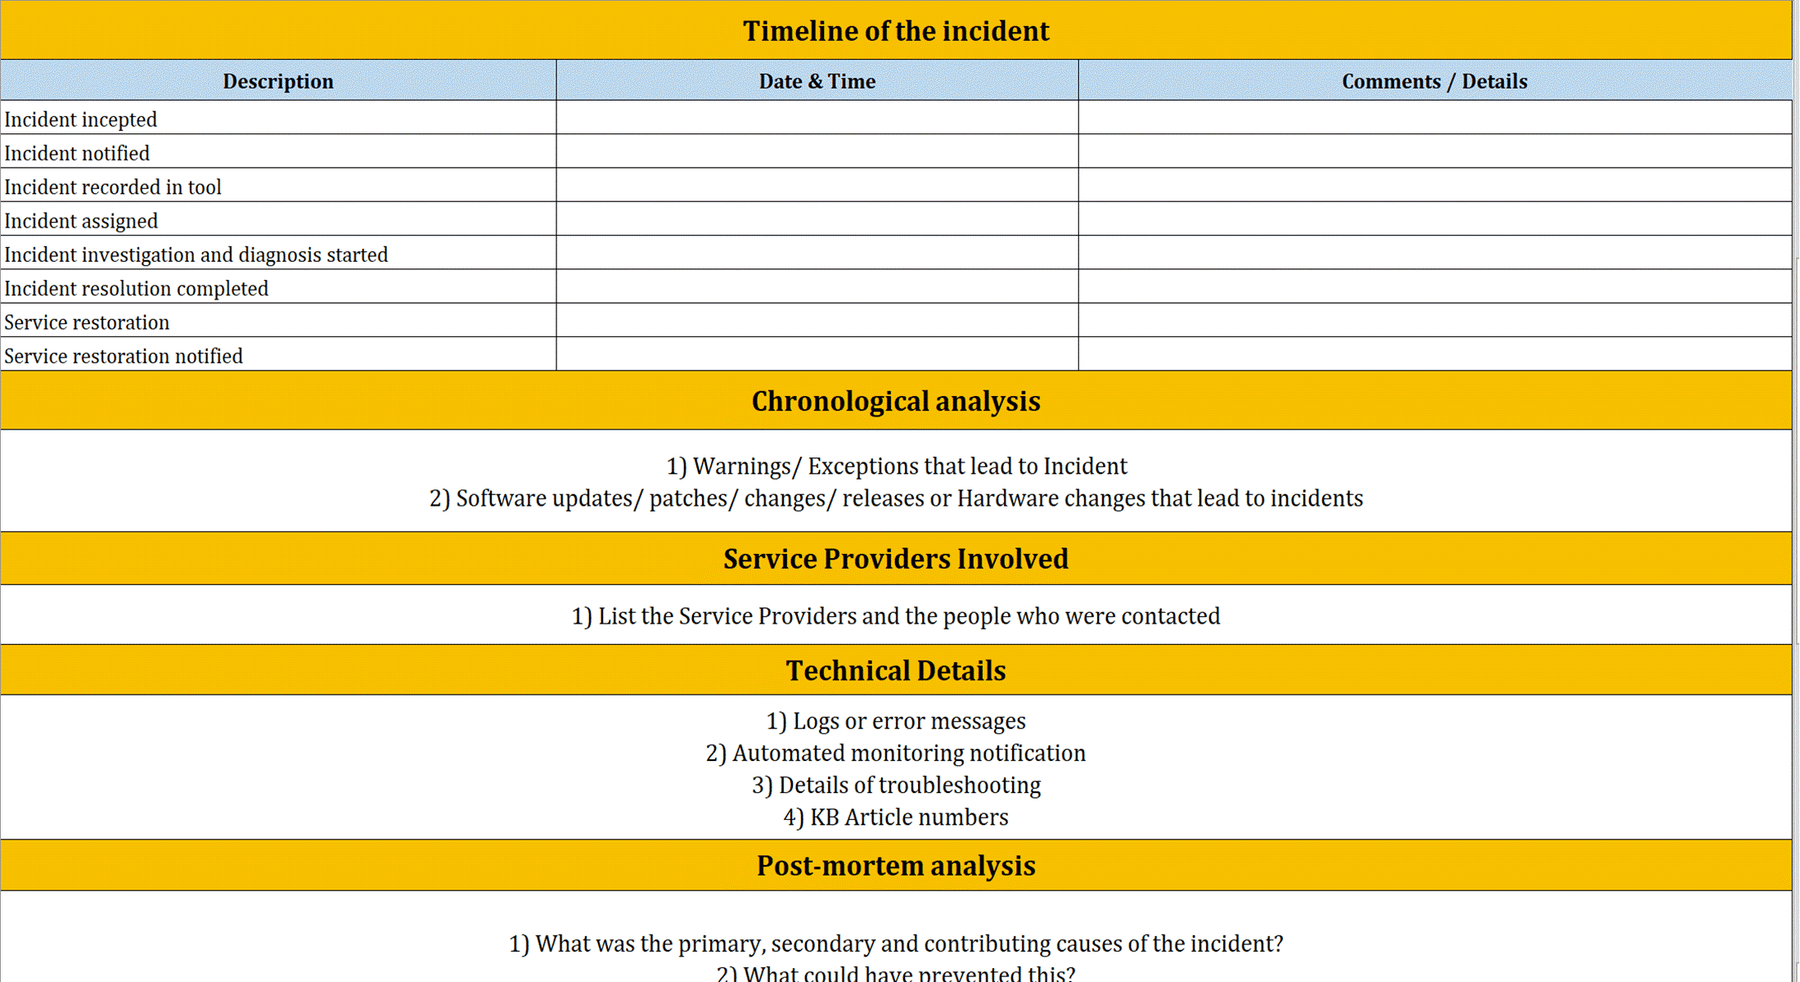
Incident Timeline
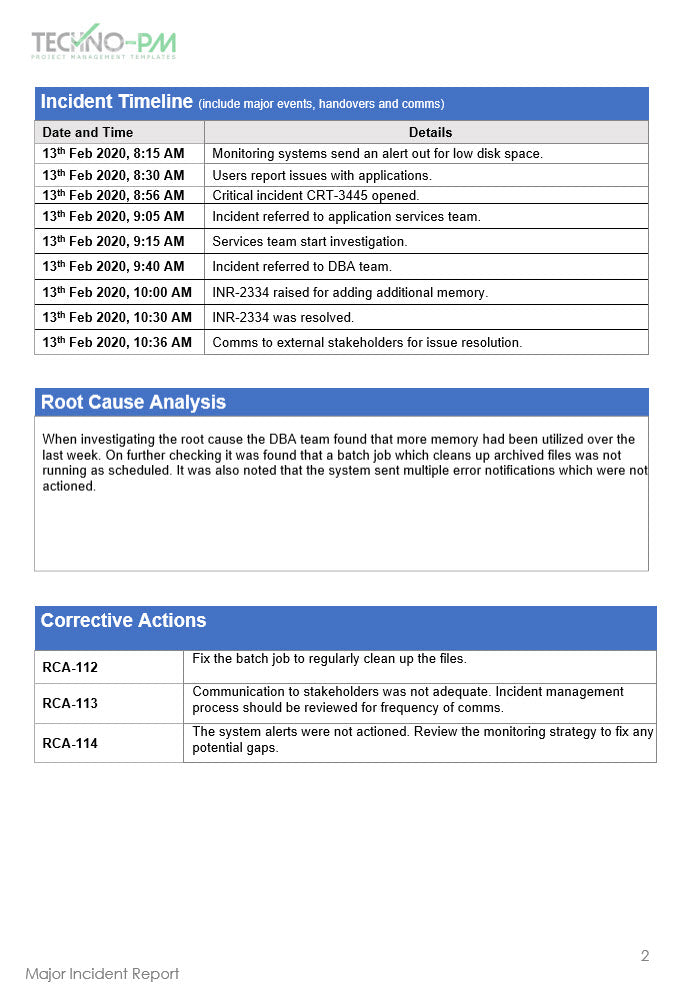
- Event Log: A chronological list of key actions taken, observations, and decisions made during the incident lifecycle. This includes detection, escalation, diagnosis, workarounds, and resolution. Each entry should include a timestamp, action, and the individual/team responsible. This provides a clear narrative of the incident response.
Technical Analysis
- Initial Diagnosis: What was initially believed to be the cause or nature of the problem.
- Symptoms: Detailed description of what was observed by users or monitoring systems.
- Root Cause Analysis (RCA): The definitive underlying cause of the incident. This section should detail the investigation process and the methodology used (e.g., 5 Whys, Fishbone Diagram).
- Contributing Factors: Any secondary issues, process gaps, or environmental conditions that exacerbated the incident.
Resolution and Recovery
- Actions Taken: Specific steps implemented to resolve the incident and restore service.
- Workarounds: Any temporary solutions provided to mitigate impact before a permanent fix.
- Permanent Fix: Description of the long-term solution implemented or planned.
- Validation Steps: How the resolution was confirmed (e.g., tests performed, monitoring verified).
Communication and Escalation
- Communication Log: Record of all internal and external communications, including notifications to stakeholders, management, and customers.
- Escalation Path: Details of how the incident was escalated within the organization and to external vendors if applicable.
Lessons Learned and Follow-up Actions
- Lessons Learned: Key insights gained from the incident, covering technical, process, and communication aspects.
- Preventative Actions: Specific steps identified to prevent recurrence (e.g., system upgrades, process changes, training).
- Improvement Opportunities: Broader suggestions for enhancing IT operations, tools, or procedures.
- Owner(s) for Follow-up Actions: Assignment of responsibility for each action item.
- Target Dates: Deadlines for completing follow-up actions.
Crafting a Comprehensive IT Major Incident Report
Filling out an It Major Incident Report Template effectively requires diligence and collaboration. It’s not a task to be rushed, but rather a structured reflection of a critical event. The process typically begins as soon as the incident is resolved or significantly mitigated, allowing responders to capture details while they are fresh.
Firstly, gather all relevant data. This includes incident logs, monitoring alerts, communication records, and notes from the incident response team. Accuracy is paramount; subjective interpretations should be backed by objective evidence. Ensure all timestamps are precise, as the timeline is crucial for understanding the flow of events and response efficacy.
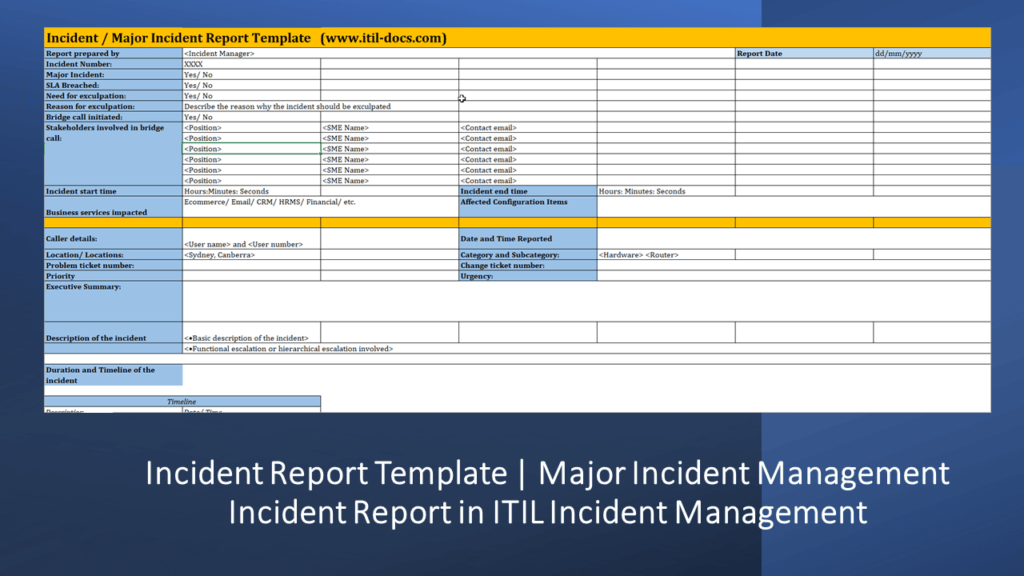
Next, focus on the technical analysis. This often involves a dedicated root cause analysis (RCA) session, bringing together experts from various domains. The RCA should aim to drill down beyond superficial symptoms to identify the true underlying issue. Was it a software bug, a hardware failure, a configuration error, a human mistake, or a combination? Documenting this thoroughly is vital for preventing future occurrences.
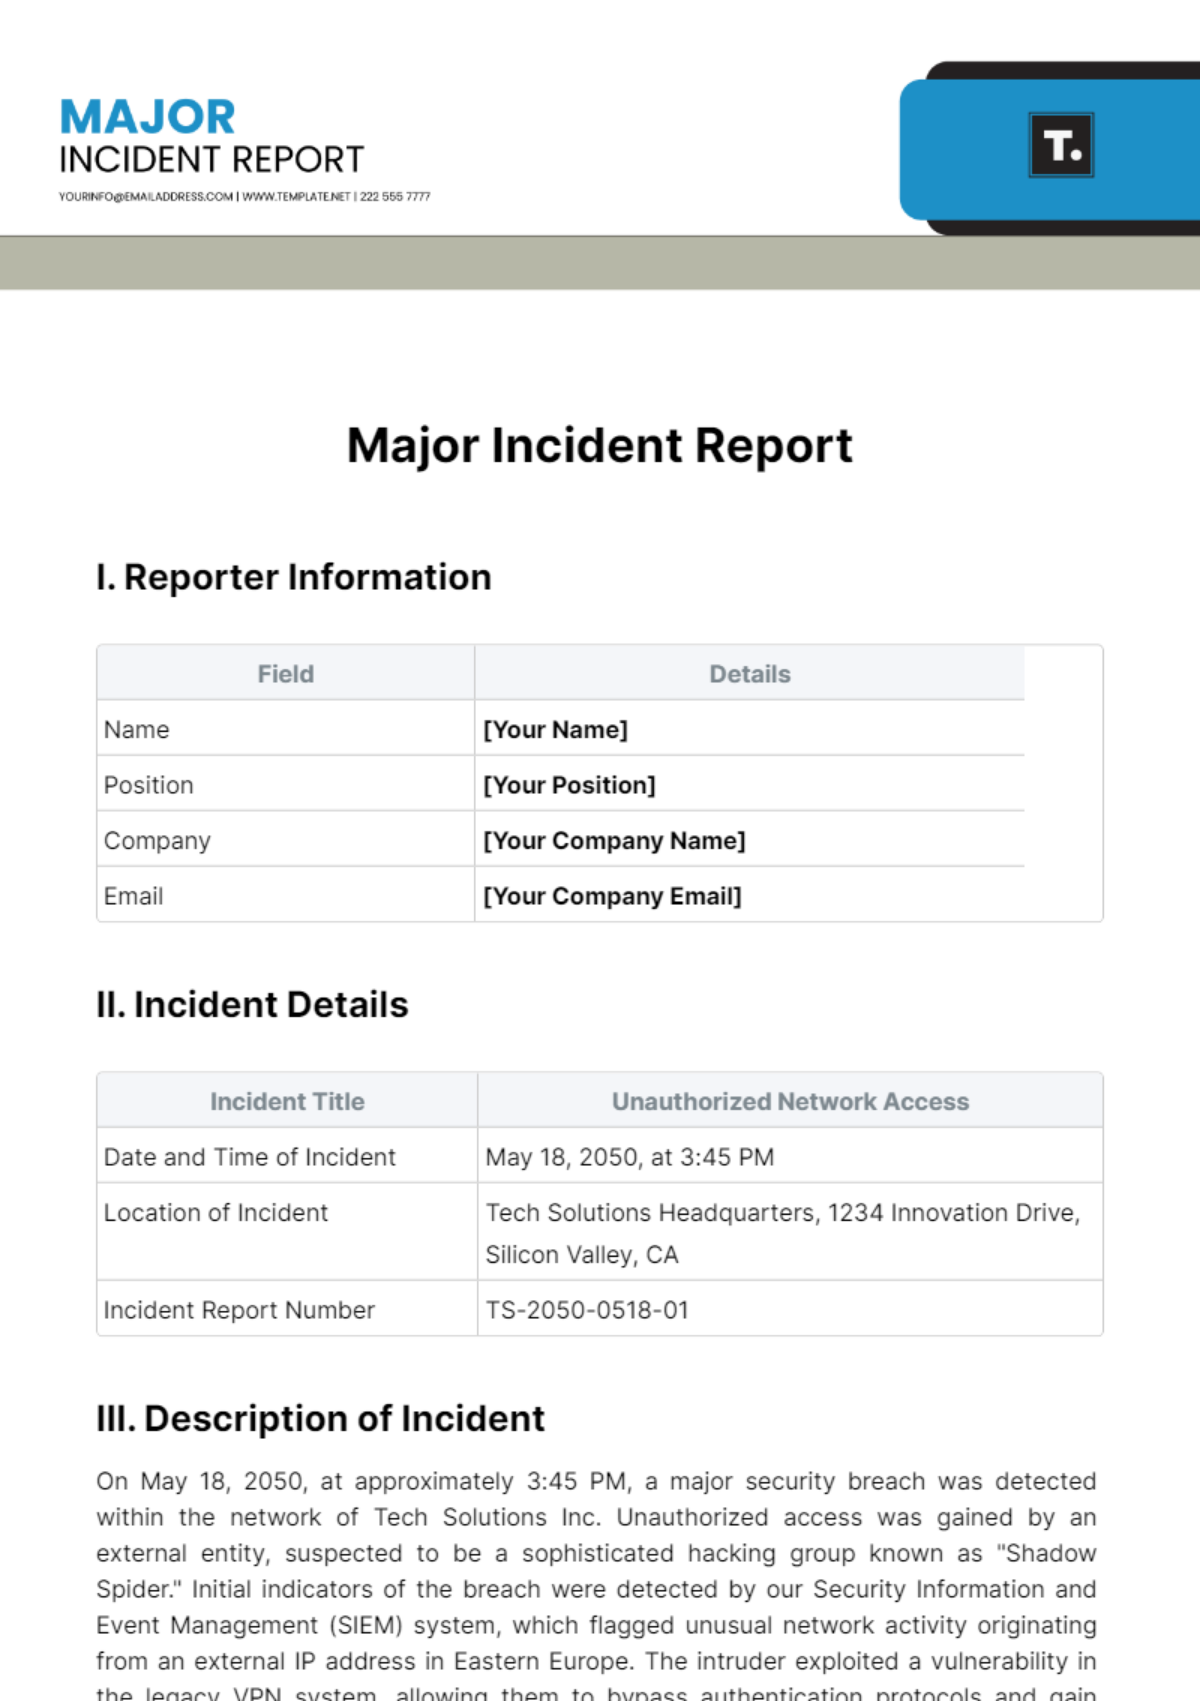
The “Lessons Learned” section is arguably the most critical part of the report. This is where the organization gleans actionable intelligence from the incident. Teams should candidly assess what went well, what could have been done better, and what systemic issues were exposed. These insights should directly translate into concrete preventative actions and improvement opportunities, each assigned an owner and a target completion date. Without this crucial step, the report remains a mere historical document rather than a catalyst for change.
Best Practices for Utilizing an It Major Incident Report Template
Maximizing the value of an It Major Incident Report Template goes beyond simply filling out the fields. It involves establishing a culture of proactive learning and continuous improvement within the organization.
Standardization and Accessibility
Ensure the template is standardized across all IT teams and easily accessible. Whether it’s integrated into an ITSM platform or stored in a shared document repository, its location and usage instructions should be clear. Regular training for staff on how to complete the template correctly will ensure consistency and quality of reporting.
Timeliness
Reports should be completed in a timely manner, ideally within a few days of incident resolution, while details are still fresh in mind. Delaying the report can lead to forgotten details, reduced accuracy, and a diminished ability to learn effectively.
Objective and Fact-Based Reporting
Encourage objective and fact-based reporting. The report should avoid blame and focus on processes, systems, and contributing factors. It’s a tool for improvement, not an arena for finger-pointing. Support all claims with evidence from logs, monitoring data, and communication records.
Regular Review and Analysis
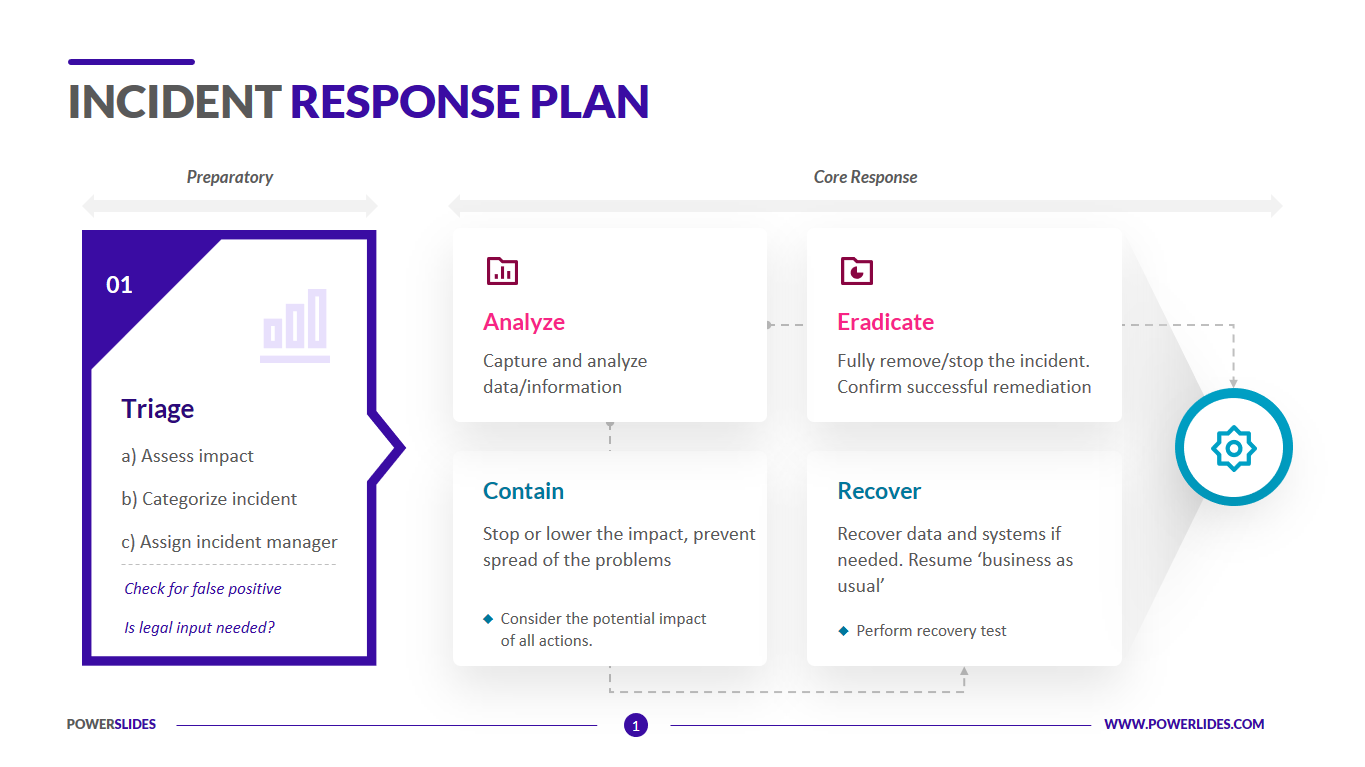
Implement a process for regular review and analysis of completed major incident reports. This could be a monthly or quarterly meeting where trends are identified, common root causes are highlighted, and the effectiveness of preventative actions is assessed. This holistic review helps in identifying systemic weaknesses and prioritizing problem management efforts.
Integration with ITSM Processes
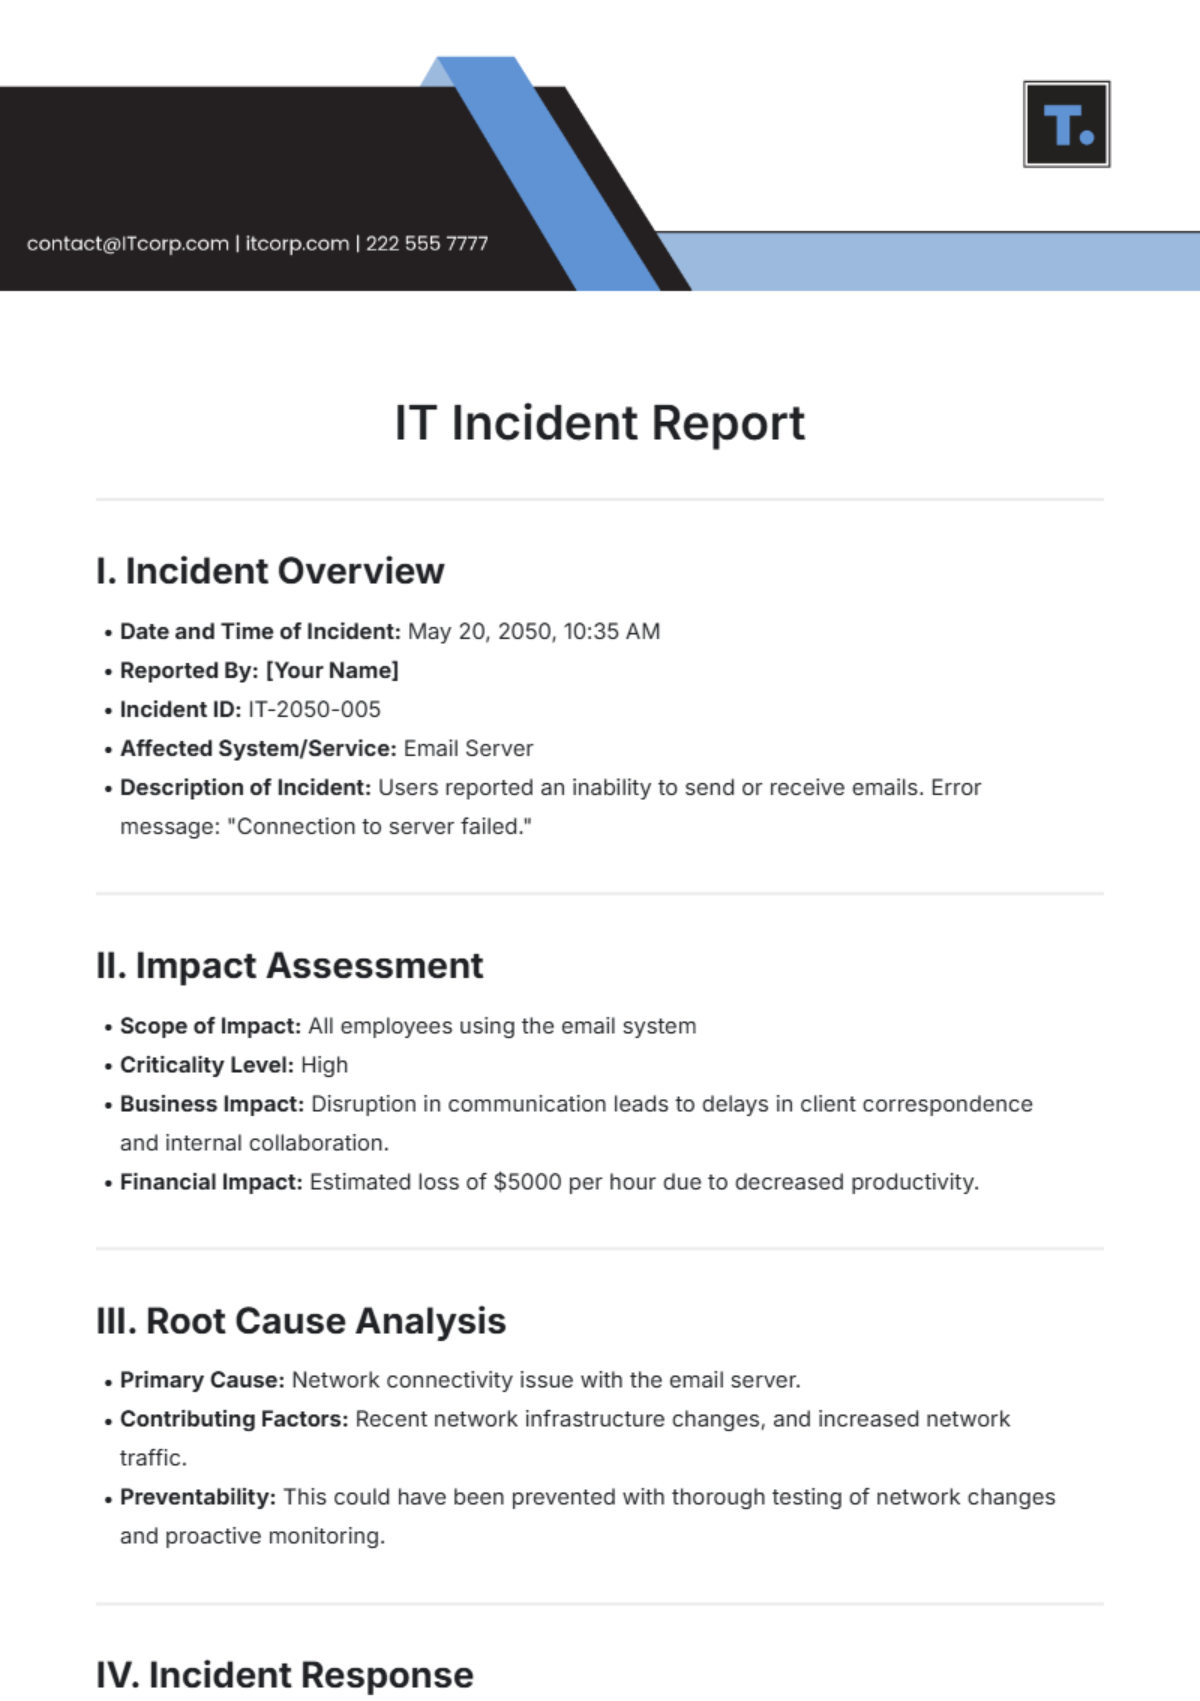
Integrate the incident reporting process with other ITSM disciplines, especially problem management, change management, and knowledge management. Insights from major incident reports should feed directly into problem records, inform future change management decisions, and enrich the organizational knowledge base, creating a virtuous cycle of improvement.
Continuous Improvement of the Template Itself
The template isn’t static. It should be subject to continuous improvement. As your organization evolves and learns, the template may need adjustments to better capture relevant information or align with new processes. Periodically review its effectiveness and gather feedback from users to refine it.
Leveraging Incident Data for Proactive IT Management
The true power of a meticulously completed It Major Incident Report Template lies in its ability to transform reactive firefighting into proactive strategic management. The aggregate data from these reports provides a rich source of intelligence for identifying patterns, predicting potential failures, and strengthening the overall IT infrastructure.
By analyzing multiple reports, IT leadership can uncover recurring themes that might not be apparent from individual incidents. For example, a series of seemingly unrelated application failures might, upon review, point to an underlying issue with a shared database or network component. This kind of insight allows for targeted investments in infrastructure upgrades, architectural improvements, or process overhauls, moving beyond symptomatic fixes to address root causes at a systemic level.
Furthermore, these reports are invaluable for risk management. They highlight vulnerabilities in systems, processes, and even staffing levels. By understanding where and why major incidents occur, organizations can develop more robust disaster recovery plans, enhance security protocols, and implement more effective monitoring strategies. The data can also be used to justify resource allocation for preventative projects, demonstrating a clear return on investment by reducing future incident costs and business disruption.
Finally, detailed incident reports contribute significantly to an organization’s knowledge management system. They provide a historical record of how specific problems were diagnosed and resolved, serving as a training resource for new staff and a reference point for existing teams. This institutional knowledge prevents “reinventing the wheel” during future incidents and accelerates resolution times, making the entire IT operation more efficient and resilient.
Conclusion
The digital landscape is inherently prone to disruption, and while perfect uptime remains an elusive ideal, the ability to effectively respond to and learn from major incidents is a hallmark of a mature IT organization. An It Major Incident Report Template is far more than a bureaucratic formality; it is a critical tool for accountability, analysis, and continuous improvement. It transforms the chaotic aftermath of a system failure into a structured pathway for growth, enabling teams to understand, mitigate, and ultimately prevent future disruptions.
By standardizing the documentation process, facilitating thorough root cause analysis, and capturing invaluable lessons learned, a well-implemented template empowers IT departments to move from a reactive stance to a proactive one. It ensures that every major incident becomes an opportunity to strengthen infrastructure, refine processes, and enhance service delivery. Embracing a comprehensive and diligently utilized incident report template is not just about recording history; it’s about actively shaping a more resilient and reliable future for your organization’s IT operations.
Related posts of "It Major Incident Report Template"
